2020 Artificial Intelligence Industry Trends


As of date some industries have been doing better than others at implementing AI. AI is lifting efficiency and performance across many diverse industries in 2020, with an array of benefits sweeping across multiple categories. As AI matures, these 9 areas and industries look like they are poised to benefit the most:


Financial Services

Banking and financial services are among the key industries benefiting from AI. The structured nature of financial data and the industry's past experiences with analytics may have made it easier for companies in this sector to implement artificial intelligence.

Many legacy organizations [in other industries] are still learning how to move from pilot projects to full operational deployments since the underlying data and architecture is very different in a pilot versus being operationalized. Financial services and insurance firms have been better at the advanced analytics on transitions since that data is well understood and managed.

In the future, the industry could see additional gains by applying AI to other areas beyond analytics, such as customer service.


Cybersecurity

Cybersecurity is likely to see big gains from AI in 2020. Already, many vendors are adding AI capabilities to their products. In its Top 10 Strategic Technology Trends for 2020, Gartner noted, "ML-based security tools can be a powerful addition to your toolkit when aimed at a specific high-value use case such as security monitoring, malware detection or network anomaly detection."

However, enterprises are likely going to need AI-based cybersecurity in order to counter new threats, which might make use of AI and machine learning themselves. As Forrester noted in its Predictions 2020, "The unfortunate reality will come to light that evil forces can adopt technologies such as AI and machine learning faster than security leaders can."


Predictive Maintenance

Many different industries, such as manufacturing, transportation, oil and gas, utilities, and even cloud computing data centers rely on complex machinery in order to stay in business. And any downtime of critical resources quickly results in significant financial losses. As a result, many organizations are investing in a combination of IoT sensors, computer vision, and/or machine learning technology to help them improve uptime by proactively identifying potential risks and scheduling maintenance in advance.

AI is improving business performance with predictive maintenance, where deep learning analyzes large amounts of high-dimensional data to detect anomalies in everything from factory assembly lines to building HVAC systems to commercial aircraft engines.


Manufacturing

Manufacturing companies are beginning to dip their toes in the AI waters. In addition to predictive maintenance, manufacturing firms are using artificial intelligence and subsets like machine learning to better manage their supply chains, forecast demand, improve quality, deliver products, and increase customer satisfaction.

However, manufacturing firms will need to improve their underlying information architecture and data management practices if they want to be successful with their AI efforts. Even when machine learning algorithms do not need any reference architecture to function (visual identification of part defects for example), application of the results of the analysis does require that knowledge and information architecture.


Logistics and Transportation

Within the transportation industry, enterprises are using artificial intelligence to help them shave precious minutes off their delivery times and dollars off their costs. Spread across a large fleet, these small gains can result in millions of dollars of savings per year, alongside increases in customer satisfaction. In logistics and transportation, AI optimizes the routing of delivery traffic, improving fuel efficiency and reducing delivery times.

In addition, the transportation industry is also turning to AI to help with the creation of advanced safety systems, semi-autonomous vehicles, and eventually, fully autonomous vehicles. The result could be safer travel for everyone.


Travel

Like the transportation industry, the travel industry is also using machine learning (a subset of AI) to enhance logistics, which can allow them to reduce prices for customers. The travel industry is seeing positive results from AI in the area of fraud detection.

Criminals often target airlines and hotels to convert stolen credit card numbers into cash. They will book travel on the stolen card, and then attempt to get a refund back to their own personal cards, pocketing the difference. Others set up far more elaborate schemes where they book travel and then attempt to resell it on the black market. AI can help identify both kinds of fraudulent transactions, resulting in cost savings for the travel industry and their customers, as well as reducing the inconvenience for people with the stolen credit cards.


B2B

Another prime area for AI implementation right now is B2B, particularly B2B sales. B2B sales are benefiting from AI as well, with speech recognition making it possible to track and optimize every customer interaction, from research to early engagement to closing the sale.

In addition to speech recognition, AI firms are also making use of advanced machine learning and analytics for a variety of purposes. For example, within B2B, pricing often differs significantly from customer to customer, and machine learning can help them better segment their customers and price more effectively. Of course, they can also use machine learning for forecasting, supply chain management, and for uncovering other insights that can help them become more competitive.


Healthcare

With coronavirus on the news every day, everyone is interested in ways to improve healthcare, and artificial intelligence seems like one promising way to speed innovation in the field. Healthcare continues to be a prime application for AI. Algorithms can assist with tasks as diverse as analysis of scans, development of vaccines, interpreting research results, and improving patient care.

Again, experts caution, however, that in order for AI to be effective within healthcare, organizations need to have good data, solid training models, and the right IT infrastructure in place to both conduct the analysis and secure sensitive data.


Retail

For online stores like Amazon, AI has become such an expected part of the sales process that people don't even notice it anymore. In retail sales, combining customer demographic and past transaction data with social media behavior observation helps generate individualized 'next product to buy' recommendations, which is now routine for many retailers. Through 2020, look for these recommendation engines to continue to improve and for retailers to find new ways to implement AI.

One interesting data point is how democratized AI adoption is. AI flattens the competitive landscape, empowering smaller businesses to leapfrog and outmaneuver much bigger ones. Expect enterprises in retail and other industries to attempt to use AI technology to better compete against larger firms.


Artists explore AI


Adjusting to technological developments is not a new concept for the art world.

Wood panels were once the standard for paintings, but by the 17th century they were largely overtaken by canvas, and the paint itself changed, too. Video art, a mainstay now, was a new phenomenon in the 1960s.

More recently, augmented reality and virtual reality have captured the imagination of artists as ways to tell stories that we could not have imagined even 20 years ago.


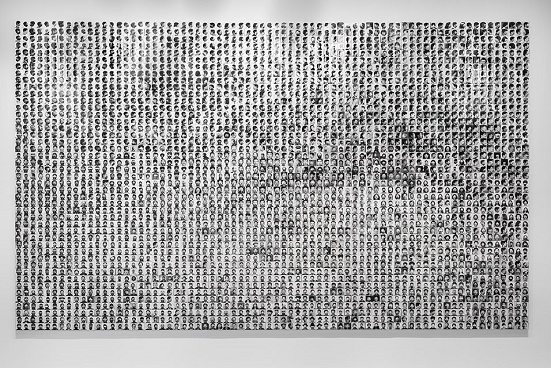
"They Took the Faces From the Accused and the Dead … (SD18)," a grid of 3,240 mug shots, by Trevor Paglen. It is part of the show "Uncanny Valley: Being Human in the Age of AI" at the de Young Museum in San Francisco.


But the rise of artificial intelligence in art, a phenomenon in recent years, has a different cast to it. Not only is AI a tool for artists, who are employing machine intelligence in fascinating ways, it is also frequently a topic to be examined — sometimes in the same piece.

And underlying many of the works is a deep unease. As Lisa Phillips, the director of New York’s New Museum, put it, the worries come down to “the prospect that machines are going to take over.” She added, “What are we unleashing?”

Even the art market was alerted to a new realm when an AI-generated portrait that was initiated by the Paris-based art collective Obvious was sold for $432,500 at Christie’s in 2018. It was like a traditional portrait of a man, but his features were smudged and blurry.

Museums and other exhibition spaces have also produced a flurry of current and coming shows involving AI that were scheduled for this spring, some of them delayed after closings because of the coronavirus pandemic.

They include a survey of the subject, “Uncanny Valley: Being Human in the Age of AI,” at the de Young Museum in San Francisco scheduled through Oct. 25; “Future Sketches,” which was on view earlier this year at Artechouse Washington and is intended to move to Artechouse’s Miami space later this year; Trevor Paglen’s photography at the Altman-Siegel Gallery in San Francisco; and “Ed Atkins: Get Life/Love’s Work” scheduled for the New Museum from June 24 to Sept. 27.

Paglen is one of the best-known artists in the AI territory. His work on it, and on the subject of state surveillance, helped him win a John D. and Catherine T. MacArthur Foundation fellowship (the “genius” grant) in 2017.

“I’ve been working on it for a while,” Paglen said.

“Once I started thinking about it, I haven’t stopped.” He is based in New York, where he has two of his three studios; the other is in Berlin.

His work at Altman-Siegel tries to connect the surveying of the American West in the 19th century with the way computers perceive the world via the data they are given — how what is officially “seen” creates power dynamics.

Paglen has a work in “Uncanny Valley,” too, called “They Took the Faces From the Accused and the Dead … (SD18),” a grid of 3,240 mug shots, used without the subjects’ consent, from the American National Standards Institute, a nonprofit group founded in 1918 that helps set agreed-upon standards across industries, including a wide array of tech fields.

The images were used to train facial-recognition programs, and Paglen uses them to question “how is data weaponized,” he said.

It has been a theme for other artists, too: Because machines have to be trained by people, what implicit biases are being passed on along the way?

“We live in a world in which things are being sorted into categories that are not inherent in nature,” Paglen said.

In addition to critiquing AI, Paglen has used it to create art. For his 2017 series “Adversarially Evolved Hallucinations,” he created an AI system that made a series of images.

“I was making my own training sets,” he said. “I built the taxonomies from scratch.” The resulting works, including a view of what a computer thinks a man looks like, may strike some as a bit spooky.

The organizer of “Uncanny Valley,” Claudia Schmuckli — the chief contemporary curator at the Fine Arts Museums of San Francisco, which includes the de Young — said that in her view, the overall tone of the works in “Uncanny Valley,” which features the work of 14 artists or collectives, was one of “concern, rather than anxiety.”

“A lot of the works in this show look at AI as an applied form of machine learning, how it actually works, not the speculative fantasy of AI,” she said. “It may be that not a lot of deep thinking has occurred about the potential consequences in the long run.”

Schmuckli moved from Houston to San Francisco in 2016, and she said it was partly the postelection revelations about hacking, Facebook and the data firm Cambridge Analytica that got her thinking. “I felt like this was an area I needed to urgently understand,” she said.

In the tech-focused Bay Area, the show has hit a nerve.

“The turnout for the opening was wholly amazing,” Schmuckli said. “We saw a lot of people who have never stepped foot in this museum before.”

The for-profit exhibition space Artechouse, with branches in New York, Washington and Miami, focuses exclusively on the nexus of art and tech, as its name suggests.

“We thought it was a niche that needed to be filled,” said co-founder Tati Pastukhova. Since its founding in 2017, about half of its shows have touched on AI in some way.

The latest such exhibition, “Future Sketches,” is a collaboration with Zach Lieberman, an artist who is also an adjunct associate professor at MIT’s Media Lab (his university bio also calls him a “hacker”).

Perhaps befitting a full-time techie, his work has a more positive spin than that of some others working with AI. His Artechouse piece “Expression Mirror,” originally created for the 2018 London Design Biennale, reads the facial expressions of a user, tracking muscle movements at 68 points on the face.

But when people look at the “mirror,” they do not see themselves. “Your face is replaced with someone’s face who has used it before,” Lieberman said. “It matches your expressions, like a smile or frown, and it learns as it interacts.” He calls this a “face action coding system,” a version of a “fingerprint.”

Lieberman said he understood why some artists plumbed the dark side of AI, because of its long-term implications and because anything to do with machines could unsettle.

“It’s this black box that you feed things into,” he said. “It’s inscrutable in some way.”

But Lieberman said he encouraged a diversity of views on matters technological. “I think it’s important to create artworks for the public to have all kinds of conversations — be they critical or playful or anything else.”

Artechouse’s other founder, Sandro Kereselidze, struck a similar note.

“Everything in the world has a positive and negative side,” he said, adding that “it’s in our power” to explore both sides of AI.

“As long as we can find the off button on the computer.”

Posted by Jai Ponnappan 


AI & Finance


The implementation of computers into different finance processes is nothing
new; high speed trading and the dominance of algorithms in the markets is a trend
that has been discussed, analyzed, and reported on at length. 

In areas such as fraud detection, risk management, credit rating and wealth advisory, AI is already augmenting or even replacing human decision makers. In fact, not deploying AI capabilities in these fields can be considered disastrous. Withthe ever-increasing amounts of data that needs to be processed, AI systems are a must-have to improve accuracy.

The key point to remember during this conversation is that, as computers become increas-
ingly sophisticated there will also be drawbacks. As increasing amounts of trading
are connected to computers, programs, and algorithms that operate without direct
human oversight and intervention there is a possibility that large swings in the mar-
ket (that volatility word) will become more frequent. 

As technological capabilities continue to improve, the amount of available data grows, and competitive pressures mount, the use of AI in finance will be pervasive. However, as with any new technology the adoption of AI brings its very own set of challenges. There are a number of concerns often cited by regulators, customers and experts which can be grouped into the following categories:


  • Bias
  • Accountability
  • Transparency

Potential causes of Bias:


  • An AI model is biased when it takes decisions that can be considered as prejudiced against certain segments of the population. One might think that these are rare occurrences – as machines should be less ‘judgmental’ than humans. Unfortunately, as has been proven last year, they tend to be far more commonplace. AI failures can happen to even some of the largest companies in the world.
  • How do these biases happen? One reason why algorithms go rogue is that the problem is framed incorrectly. For instance, if an AI system calculating the creditworthiness of a customer is tasked to optimize profits, it could soon get into predatory behavior and look for people with low credit scores to sell subprime loans. This practice may be frowned upon by society and considered unethical, but the AI does not understand such nuances.
  • Another reason for unintended bias can be the lack of social awareness: The data fed into the system already contains the biases and prejudice that manifests the social system. The machine neither understands these biases nor can it consider removing them, it just tries to optimize the model for the biases in the system.
  • Finally, the data itself may not be a good representative sample. When there are low samples from certain minority segments, and some of these data points turn out to be bad, the algorithms could make some sweeping generalizations based on the limited data it has. This is not unlike any human decisions influenced by availability heuristics.

Accountability Challenges:


  • The question who’s responsible if AI makes a wrong decision. If a self-driving car causes an accident, should it be the fault of the owner who didn’t maintain the car correctly, or did not respond when the algorithm made a bad call? Or is it purely an algorithmic issue? What about our previous example of predatory pricing – within which time frame is the firm employing this algorithm supposed to know that something is amiss and fix it? And to what extent are they responsible for the damages?
  • These are very important regulatory and ethical issues which need to be addressed.There are risks related to the technology which need to be carefully managed, especially when consumers are affected. This is why it’s important to employ the concept of algorithmic accountability, which revolves around the central tenet that the operators of the algorithm should put in place sufficient controls to make sure the algorithm performs as expected.
Missing Transparency:


  • Many algorithms suffer from a lack of transparency and interpretability, making it difficult to identify how and why they come to particular conclusions. As a result, it can be challenging to identify model bias or discriminatory behavior. 
  • It’s fair to say that the lack of transparency and the prevalence of black box models is the underlying cause for the two challenges outlined above.


From anecdotal evidence and review of market commentary, it does seem that the
increasing technological dominance of trading may be leading to several different
effects. 


First, while volatility while judged by historically levels, has been at low levels
in the 2015–2018 time period this does not provide the entire picture. The decrease
in volatility may not, as some has speculated, be associated with the increased effi-
ciency generated by algorithmic trading programs, but rather a related trend. ETFs,
passive investing tools, and the growing (trillions as of this writing) assets invested
in these options may also be having an outsized impact on volatility and training
patterns. Put simply, as larger and larger percentages of investors and funds are
investing in similar, if not identical, trading tools and platforms, this may very well
have a depressive impact on market volatility. 

This may very well seem like a positive effect to retail investors with jitters linked to increases in market volatility, but masks an underlying problem. If investing decisions are made outside of human

oversight and supervision this can inadvertently lead to market selloffs, runoffs, and
other actions that do not reflect the underlying economic reality.

This is a tremendous opportunity for financial advisors, planners, and other advi-
sory focused finance professionals to offer real time, real world, and actionable
business insights to clients and customers in a market that can seem as it operates
outside the realm of normal possibility. Volatility, although depressed during 2017,
seems to have returned to the market with force in 2018, emphasizes the important
of having a professional behind the wheel of various automated services and pro-
cesses. Simply executing certain processes, trades, and business transactions faster
will offer no benefit to either the organization or clients if those said processes are
poorly written or designed. 

In order for practitioners to effectively leverage technology they must understand not only how the technology itself works, but also how it can – and should be – applied to the business decision making process itself.

Another area where can, and already is, having an impact on the financial ser-
vices landscape is the realm of ad hoc and management reporting, which constitutes
a rather large percentage of the actual work performed by professionals working in
the space. Generating reports for management and supervisors simultaneously
forms a plurality of work performed by many accounting professionals and a way
that professionals can quantitatively add value to the organization. Despite of this,
one of the key issues raised and problems associated with internal management
reporting, or ad hoc reporting, is that data is not generated consistently, systems do
not communicate with each other, and there are inevitably time lags between when
different classes of information are generated. 

In the context of accounting professionals seeking to elevate both themselves and the work performed internally, the amount of time spent correcting errors, manually adjusting entries and
information deprives professionals of the time necessary to instead focus on higher
level activities. In other words, if accountants are spending too much time manually
creating reports and fixing errors, those same professionals will never be able to
achieve the oft-cited role as strategic advisor or business partner.

Audit and attestation work, discussed previously and to be expanded upon
throughout this text, represents a prime area where artificial intelligence will have
an impact on the profession. Currently, the entire process of auditing has several
pain points, namely the fact that the final audit opinion is heavily (if not exclusively)
reliant on expanding on findings generated from a small sample of organizational
information. 

Even with the subsequent analytical procedures and substantive tests
added into the audit examination process, audit failures are all too common. AI
tools, such as those represented by the partnership between IBM Watson and
KPMG, are already having an dramatic impact on audit testing, procedures, and
how auditors interact with both clients and future clients. This evolution and transi-
tion, from a compliance oriented function that focused exclusively on financial
information, to a more comprehensive process that can operate on a continuous
basis also connects to several other trends. Introduced here, but examined in more
detail later in this book, the connection between assurance work, non-financial
information, and the importance of this data to the decision making process opens
up a proverbial work of opportunities for accounting practitioners.

Tax reporting and the discussion of taxation issues are normally not associated
with pleasant news or something that management professionals, but that is not some-
thing that should be perceived as the final state of the conversation. Specifically, and
even in the current environment beset by changes in tax reporting, this debate and
analysis can, and should, be perceived both as an opportunity and part of the continu-
ous management dialogue. Put simply, although the Tax Cuts and Jobs Acts was
passed right at the end of 2017 – December 22nd to be specific – the ripple effects as
a result of this legislation are still being analyzed and processed by both individuals
and organizations. Processing the sheer number of changes, running scenario analy-
ses, and putting the results of these analyses into a format and report that are under-
standable for management decision making is both a role accounting professionals
should play, and a function enabled by AI tools. Taxes have an impact on the bottom
line, will continue to guide investment and operational decisions moving forward, and
will play a prominent role in the implementation and analysis of AI.

For financial institutions, it is clear that guidelines need to be put in place to help avoid bias, ensure safety and privacy, and to make the technology accountable and explainable. AI doesn’t have to be a black box – there are ways to make it more intuitive to humans such as Explainable AI (XAI).

XAI is a broad term which covers systems and tools to increase the transparency of the AI decision making process to humans. The major benefit of this approach is that it provides insights into the data, variables and decision points used to make a recommendation. Since 2017, a lot of effort has been put into XAI to solve the black box problem. DARPA has been a pioneer in the effort to create systems which facilitate XAI and it has since gained industry-wide as well as academic interest. In the past year, we have seen significant increase in the adoption of XAI, with Google, Microsoft and other large technology players starting to create such systems.

There are still challenges to XAI. The technology is still nascent. And there are concerns that explainability compromises accuracy, or that adopting XAI compromises the IP of the firm. However, the success of AI will depend on our ability to create trust in the technology and to drive acceptance among users, customers and the broader public. XAI can be a game changer as it will help increase transparency and overcome many of the hurdles that currently prevent its adoption.


Coronavirus treatment trial uses AI to speed results

The first hospital network in the U.S. has joined an international clinical trial using artificial intelligence to help determine which treatments for patients with the novel coronavirus are most effective on an on-going basis.


Why it matters: In the midst of a pandemic, scientists face dueling needs: to find treatments quickly and to ensure they are safe and effective. By using this new type of adaptive platform, doctors hope to collect clinical data that will help more quickly determine what actually works.
“The solution is to find an optimal trade-off between doing something now, such as prescribing a drug off-label, or waiting until traditional clinical trials are complete.”
— Derek Angus, senior trial investigator and professor at University of Pittsburgh School of Medicine, told a press briefing
State of play: No treatments have been approved for COVID-19 yet. Researchers have made headway in mapping how the virus attaches and infects human cells — helping "guide drug developers, atom by atom, in devising safe and effective ways to treat COVID-19," National Institutes of Health director Francis Collins writes.
  • But new drugs take a long time to develop, partly because they must first be tested for safety before broadening to test for safety and efficacy.
  • While many companies are working on new treatments, others have focused on testing drugs for other conditions that have already met safety requirements.
What's new: The University of Pittsburgh Medical Center (UPMC) is the first American hospital system to join an international treatment trial called REMAP-COVID19, which is enrolling patients with COVID-19 in North America, Europe, Australia and New Zealand so far.


How it works: Starting Thursday, UPMC's system of 40 hospitals began offering the trial to patients who have moderate to severe complications from COVID-19, Angus said.
  • Patients in the trial will receive their current standard of care. About 12.5% will receive placebo at the launch and the rest will be randomly selected to multiple interventions with one or more antibiotics, antivirals, steroids, and medicines that regulate the immune system, including the drug hydroxychloroquine.
  • The platform, based on an existing one called REMAP-CAP, is integrated with UPMC's electronic health records and the data collected via a worldwide machine-learning system that continuously determines what combination of therapies is performing best.
  • As more data is collected, more patients will be steered toward the therapies doing well, Angus said.
  • The adaptive trial format, published Thursday in the journal Annals of the American Thoracic Society, can allow new treatments to be rolled into the trial.
"This idea came to us after the H1N1 [epidemic], when everyone scrambled to do traditional trials" but by the time those were established, the outbreak had moved on, Angus said. "We asked, how we can do this better."
The big picture: There are more than 400 listed clinical trials for treatments, therapies and vaccines related to COVID-19.


Healthy skepticism of Artificial Intelligence & Coronavirus


The COVID-19 outbreak has spurred considerable news coverage about the ways artificial intelligence (AI) can combat the pandemic’s spread. Unfortunately, much of it has failed to be appropriately skeptical about the claims of AI’s value. Like many tools, AI has a role to play, but its effect on the outbreak is probably small. While this may change in the future, technologies like data reporting, telemedicine, and conventional diagnostic tools are currently far more impactful than AI.


1. LOOK TO THE SUBJECT-MATTER EXPERTS

Still, various news articles have dramatized the role AI is playing in the pandemic by overstating what tasks it can perform, inflating its effectiveness and scale, neglecting the level of human involvement, and being careless in consideration of related risks. In fact, the COVID-19 AI-hype has been diverse enough to cover the greatest hits of exaggerated claims around AI. And so, framed around examples from the COVID-19 outbreak, here are eight considerations for a skeptic’s approach to AI claims.
No matter what the topic, AI is only helpful when applied judiciously by subject-matter experts—people with long-standing experience with the problem that they are trying to solve. Despite all the talk of algorithms and big data, deciding what to predict and how to frame those predictions is frequently the most challenging aspect of applying AI. Effectively predicting a badly defined problem is worse than doing nothing at all. Likewise, it always requires subject matter expertise to know if models will continue to work in the future, be accurate on different populations, and enable meaningful interventions.
In the case of predicting the spread of COVID-19, look to the epidemiologists, who have been using statistical models to examine pandemics for a long time. Simple mathematical models of smallpox mortality date all the way back to 1766, and modern mathematical epidemiology started in the early 1900s. The field has developed extensive knowledge of its particular problems, such as how to consider community factors in the rate of disease transmission, that most computer scientists, statisticians, and machine learning engineers will not have.
“There is no value in AI without subject-matter expertise.”
It is certainly the case that some of the epidemiological models employ AI. However, this should not be confused for AI predicting the spread of COVID-19 on its own. In contrast to AI models that only learn patterns from historical data, epidemiologists are building statistical models that explicitly incorporate a century of scientific discovery. These approaches are very, very different. Journalists that breathlessly cover the “AI that predicted coronavirus” and the quants on Twitter creating their first-ever models of pandemics should take heed: There is no value in AI without subject-matter expertise.


2. AI NEEDS LOTS OF DATA

The set of algorithms that conquered Go, a strategy board game, and “Jeopardy!” have accomplishing impressive feats, but they are still just (very complex) pattern recognition. To learn how to do anything, AI needs tons of prior data with known outcomes. For instance, this might be the database of historical “Jeopardy!” questions, as well as the correct answers. Alternatively, a comprehensive computational simulation can be used to train the model, as is the case for Go and chess. Without one of these two approaches, AI cannot do much of anything. This explains why AI alone can’t predict the spread of new pandemics: There is no database of prior COVID-19 outbreaks (as there is for the flu)
To even attempt this, companies would need to collect extensive thermal imaging data from people while simultaneously taking their temperature with a conventional thermometer. In addition to attaining a sample diverse in age, gender, size, and other factors, this would also require that many of these people actually have fevers—the outcome they are trying to predict. It stretches credibility that, amid a global pandemic, companies are collecting data from significant populations of fevered persons. While there are other potential ways to attain pre-existing datasets, questioning the data sources is always a meaningful way to assess the viability of an AI system.


3. DON’T TRUST AI’S ACCURACY

The company Alibaba claims it can use AI on CT imagery to diagnose COVID-19, and now Bloomberg is reporting that the company is offering this diagnostic software to European countries for free. There is some appeal to the idea. Currently, COVID-19 diagnosis is done through a process called polymerase chain reaction (PCR), which requires specialized equipment. Including shipping time, it can easily take several days, whereas Alibaba says its model is much faster and is 96% accurate.
However, it is not clear that this accuracy number is trustworthy. A poorly kept secret of AI practitioners is that 96% accuracy is suspiciously high for any machine learning problem. If not carefully managed, an AI algorithm will go to extraordinary lengths to find patterns in data that are associated with the outcome it is trying to predict. However, these patterns may be totally nonsensical and only appear to work during development. In fact, an inflated accuracy number can actually be an important sign that an AI model is not going to be effective out in the world. That Alibaba claims its model works that well without caveat or self-criticism is suspicious on its face.
“[A]n inflated accuracy number can actually be an important sign that an AI model is not going to be effective out in the world.”
In addition, accuracy alone does not indicate enough to evaluate the quality of predictions. Imagine if 90% of the people in the training data were healthy, and the remaining 10% had COVID-19. If the model was correctly predicting all of the healthy people, a 96% accuracy could still be true—but the model would still be missing 40% of the infected people. This is why it’s important to also know the model’s “sensitivity,” which is the percent of correct predictions for individuals who have COVID-19 (rather than for everyone). This is especially important when one type of mistaken prediction is worse than the other, which is the case now. It is far worse to mistakenly suggest that a person with COVID-19 is not sick (which might allow them to continue infecting others) than it is to suggest a healthy person has COVID-19.
Broadly, this is a task that seems like it could be done by AI, and it might be. Emerging research suggests that there is promise in this approach, but the debate is unsettled. For now, the American College of Radiology says that “the findings on chest imaging in COVID-19 are not specific, and overlap with other infections,” and that it should not be used as a “first-line test to diagnose COVID-19.” Until stronger evidence is presented and AI models are externally validated, medical providers should not consider changing their diagnostic workflows—especially not during a pandemic.


4. REAL-WORLD DEPLOYMENT DEGRADES AI PERFORMANCE

The circumstances in which an AI system is deployed can also have huge implications for how valuable it really is. When AI models leave development and start making real-world predictions, they nearly always degrade in performance. In evaluating CT scans, a model that can differentiate between healthy people and those with COVID-19 might start to fail when it encounters patients who are sick with the regular flu (and it is still flu season in the United States, after all). A drop of 10% accuracy or more during deployment would not be unusual.
In a recent paper about the diagnosis of malignant moles with AI, researchers noticed that their models had learned that rulers were frequently present in images of moles known to be malignant. So, of course, the model learned that images without rulers were more likely to be benign. This is a learning pattern that leads to the appearance of high accuracy during model development, but it causes a steep drop in performance during the actual application in a health-care setting. This is why independent validation is absolutely essential before using new and high-impact AI systems.
“When AI models leave development and start making real-world predictions, they nearly always degrade in performance.”
This should engender even more skepticism of claims that AI can be used to measure body temperature. Even if a company did invest in creating this dataset, as previously discussed, reality is far more complicated than a lab. While measuring core temperature from thermal body measurements is imperfect even in lab conditions, environmental factors make the problem much harder. The approach requires an infrared camera to get a clear and precise view of the inner face, and it is affected by humidity and the ambient temperature of the target. While it is becoming more effective, the Centers for Disease Control and Prevention still maintain that thermal imaging cannot be used on its own—a second confirmatory test with an accurate thermometer is required.


5. MOST PREDICTIONS MUST ENABLE AN INTERVENTION TO REALLY MATTER

In high-stakes applications of AI, it typically requires a prediction that isn’t just accurate, but also one that meaningfully enables an intervention by a human. This means sufficient trust in the AI system is necessary to take action, which could mean prioritizing health-care based on the CT scans or allocating emergency funding to areas where modeling shows COVID-19 spread.
With thermal imaging for fever-detection, an intervention might imply using these systems to block entry into airports, supermarkets, pharmacies, and public spaces. But evidence shows that as many as 90% of people flagged by thermal imaging can be false positives. In an environment where febrile people know that they are supposed to stay home, this ratio could be much higher. So, while preventing people with fever (and potentially COVID-19) from enabling community transmission is a meaningful goal, there must be a willingness to establish checkpoints and a confirmatory test, or risk constraining significant chunks of the population.
This should be a constant consideration for implementing AI systems, especially those used in governance. For instance, the AI fraud-detection systems used by the IRS and the Centers for Medicare and Medicaid Services do not determine wrongdoing on their own; rather, they prioritize returns and claims for auditing by investigators. Similarly, the celebrated AI model that identifies Chicago homes with lead paint does not itself make the final call, but instead flags the residence for lead paint inspectors.


6. AI IS FAR BETTER AT MINUTE DETAILS THAN BIG, RARE EVENTS

Wired ran a piece in January titled “An AI Epidemiologist Sent the First Warnings of the Wuhan Virus” about a warning issued on Dec. 31 by infectious disease surveillance company, BlueDot. One blog post even said the company predicted the outbreak “before it happened.” However, this isn’t really true. There is reporting that suggests Chinese officials knew about the coronavirus from lab testing as early as Dec. 26. Further, doctors in Wuhan were spreading concerns online (despite Chinese government censorship) and the Program for Monitoring Emerging Diseases, run by human volunteers, put out a notification on Dec. 30.
That said, the approach taken by BlueDot and similar endeavors like HealthMap at Boston Children’s Hospital aren’t unreasonable. Both teams are a mix of data scientists and epidemiologists, and they look across health-care analyses and news articles around the world and in many languages in order to find potential new infectious disease outbreaks. This is a plausible use case for machine learning and natural language processing and is a useful tool to assist human observers. So, the hype, in this case, doesn’t come from skepticism about the feasibility of the application, but rather the specific type of value it brings.
“AI is unlikely to build the contextual understanding to distinguish between a new but manageable outbreak and an emerging pandemic of global proportions.”
Even as these systems improve, AI is unlikely to build the contextual understanding to distinguish between a new but manageable outbreak and an emerging pandemic of global proportions. AI can hardly be blamed. Predicting rare events is just very hard, and AI’s reliance on historical data does it no favors here. However, AI does offer quite a bit of value at the opposite end of the spectrum—providing minute detail.
For example, just last week, California Gov. Gavin Newsom explicitly praised BlueDot’s work to model the spread of the coronavirus to specific zip codes, incorporating flight-pattern data. This enables relatively precise provisioning of funding, supplies, and medical staff based on the level of exposure in each zip code. This reveals one of the great strengths of AI: its ability to quickly make individualized predictions when it would be much harder to do so individually. Of course, individualized predictions require individualized data, which can lead to unintended consequences.


7. THERE WILL BE UNINTENDED CONSEQUENCES

AI implementations tend to have troubling second-order consequences outside of their exact purview. For instance, consolidation of market power, insecure data accumulation, and surveillance concerns are very common byproducts of AI use. In the case of AI for fighting COVID-19, the surveillance issues are pervasive. In South Korea, the neighbors of confirmed COVID-19 patients were given details of that person’s travel and commute history. Taiwan, which in many ways had a proactive response to the coronavirus, used cell phone data to monitor individuals who had been assigned to stay in their homes. Israel and Italy are moving in the same direction. Of exceptional concern is the deployed social control technology in China, which nebulously uses AI to individually approve or deny access to public space.
Government action that curtails civil liberties during an emergency (and likely afterwards) is only part of the problem. The incentives that markets create can also lead to long-term undermining of privacy. At this moment, Clearview AI and Palantir are among the companies pitching mass-scale surveillance tools to the federal government. This is the same Clearview AI that scraped the web to make an enormous (and unethical) database of faces—and it was doing so as a reaction to an existing demand in police departments for identifying suspects with AI-driven facial recognition. If governments and companies continue to signal that they would use invasive systems, ambitious and unscrupulous start-ups will find inventive new ways to collect more data than ever before to meet that demand.


8. DON’T FORGET: AI WILL BE BIASED

In new approaches to using AI in high-stakes circumstances, bias should be a serious concern. Bias in AI models results in skewed estimates across different subgroups, such as women, racial minorities, or people with disabilities. In turn, this frequently leads to discriminatory outcomes, as AI models are often seen as objective and neutral.
While investigative reporting and scientific research has raised awareness about many instances of AI bias, it is important to realize that AI bias is more systemic than anecdotal. An informed AI skeptic should hold the default assumption that AI models are biased, unless proven otherwise.
“An informed AI skeptic should hold the default assumption that AI models are biased, unless proven otherwise.”
For example, a preprint paper suggests it is possible to use biomarkers to predict mortality risk of Wuhan COVID-19 patients. This might then be used to prioritize care for those most at risk—a noble goal. However, there are myriad sources of potential bias in this type of prediction. Biological associations between race, gender, age, and these biomarkers could lead to biased estimates that don’t represent mortality risk. Unmeasured behavioral characteristics can lead to biases, too. It is reasonable to suspect that smoking history, more common among Chinese men and a risk factor for death by COVID-19, could bias the model into broadly overestimating male risk of death.
Especially for models involving humans, there are so many potential sources of bias that they cannot be dismissed without investigation. If an AI model has no documented and evaluated biases, it should increase a skeptic’s certainty that they remain hidden, unresolved, and pernicious.


THE FUTURE OF AI SYSTEMS IS MORE PROMISING

While this article takes a deliberately skeptical perspective, the future impact of AI on many of these applications is bright. For instance, while diagnosis of COVID-19 with CT scans is of questionable value right now, the impact that AI is having on medical imaging is substantial. Emerging applications can evaluate the malignancy of tissue abnormalities, study skeletal structures, and reduce the need for invasive biopsies.
Other applications show great promise, though it is too soon to tell if they will meaningfully impact this pandemic. For instance, AI-designed drugs are just now starting human trials. The use of AI to summarize thousands of research papers may also quicken medical discoveries relevant to COVID-19.

AI is a widely applicable technology, but its advantages need to be hedged in a realistic understanding of its limitations. To that end, the goal of this paper is not to broadly disparage the contributions that AI can make, but instead to encourage a critical and discerning eye for the specific circumstances in which AI can be meaningful.


COVID-19 High Performance Computing Consortium


The COVID-19 High Performance Computing Consortium Bringing together the Federal government, industry, and academic leaders to provide access to the world’s most powerful high-performance computing resources in support of COVID-19 research. Over 402 petaflops, 105,334 nodes, 3,539,044 CPU cores, 41,286 GPUs, and counting.


The world's leading medical researchers are rushing to find a treatment for COVID-19 with the help of the most powerful and advanced supercomputers in the world.
Researchers aross the globe are submitting potential treatments and cures to the COVID-19 High Performance Computing Consortium.
The consortium, using a network of supercomputers and laboratotires, can run through simulations to narrow down or rule out drug compounds to use in a cure much faster than traditional methods.
"It's a means by which one can begin to analyze tremendously complex or large problems," says Vice President of Technical Computing at IBM Cognitive Systems Dave Turek. "Pharmaceutical companies may have billions of compounds that could be potential drugs."
Any researcher can submit proposals to the consortium for the supercomputes to run through.
"So, there are very novel techniques, specifically using A.I. on these supercomputers that are beginnign to speculate about new kinds of molecules that could be created to treat COVID-19," says Turek.

The COVID-19 High Performance Computing Consortium is a unique private-public effort spearheaded by the White House Office of Science and Technology Policy, the U.S. Department of Energy and IBM to bring together federal government, industry, and academic leaders who are volunteering free compute time and resources on their world-class machines.


Consortium partners include:

  • Industry
    • IBM
    • Amazon Web Services
    • AMD
    • Google Cloud
    • Hewlett Packard Enterprise
    • Microsoft
    • NVIDIA
  • Academia
    • Massachusetts Institute of Technology
    • Rensselaer Polytechnic Institute
    • University of Illinois
    • University of Texas at Austin
    • University of California - San Diego
    • Carnegie Mellon University
    • University of Pittsburgh
    • Indiana University
    • University of Wisconsin-Madison
  • Department of Energy National Laboratories
    • Argonne National Laboratory
    • Lawrence Livermore National Laboratory
    • Los Alamos National Laboratory
    • Oak Ridge National Laboratory
    • National Energy Research Scientific Computing Center
    • Sandia National Laboratories
  • Federal Agencies
    • National Science Foundation
      • XSEDE
      • Pittsburgh Supercomputing Center (PSC)
      • Texas Advanced Computing Center (TACC)
      • San Diego Supercomputer Center (SDSC)
      • National Center for Supercomputing Applications (NCSA)
      • Indiana University Pervasive Technology Institute (IUPTI)
      • Open Science Grid (OSG)
      • National Center for Atmospheric Research (NCAR)
    • NASA
Researchers are invited to submit COVID-19 related research proposals to the consortium via this online portal, which will then be reviewed for matching with computing resources from one of the partner institutions. An expert panel comprised of top scientists and computing researchers will work with proposers to assess the public health benefit of the work, with emphasis on projects that can ensure rapid results.
Fighting COVID-19 will require extensive research in areas like bioinformatics, epidemiology, and molecular modeling to understand the threat we’re facing and form strategies to address it. This work demands a massive amount of computational capacity. The COVID-19 High Performance Computing Consortium helps aggregate computing capabilities from the world's most powerful and advanced computers to help COVID-19 researchers execute complex computational research programs to help fight the virus.
About the Consortium, the HPC Systems & How to Join
Consortium members manage a range of computing capabilities that span from small clusters to some of the largest supercomputers in the world. As a member, you would support this crucial work by not only offering your computational resources, but also your deep technical capabilities and expertise to help COVID-19 researchers execute complex computational research programs. We hope that you will join us in this crucial mission.
We are currently providing broad access to portions of over 30 supercomputing systems, representing over over 402 petaflops, 105,334 nodes, 3,539,044 CPU cores, 41,286 GPUs, and counting. Their basic specifications are described below. Additional resources will be added as our consortium grows; please check back for updates.